
Add the Eyes SDK to an existing Playwright test, and Visual AI replaces toHaveScreenshot() assertions with checks that ignore anti-aliasing, font rendering, and other rendering noise, so a failure means the UI actually changed.
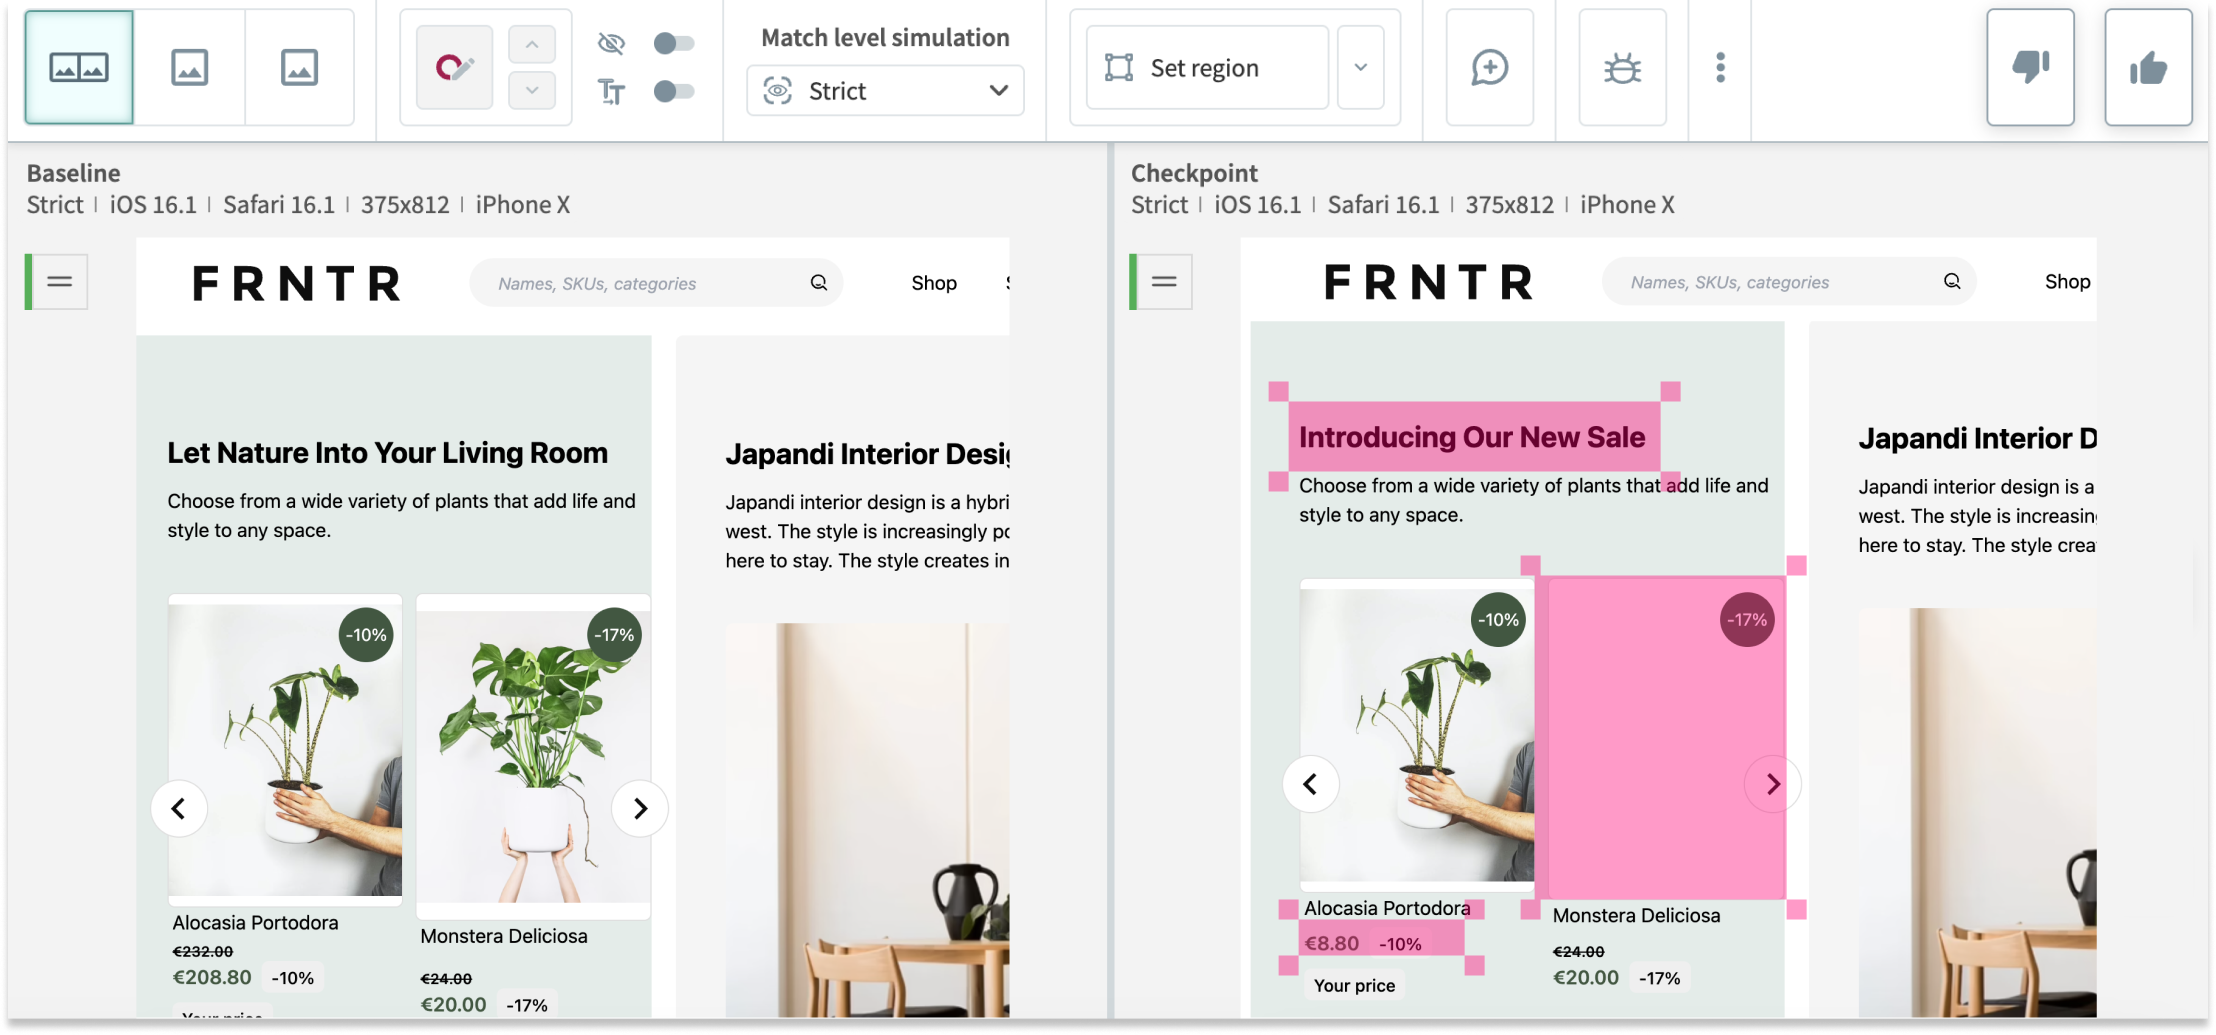
Playwright's built-in screenshot comparison flags every anti-aliasing shift and font-rendering difference. Visual AI ignores what a person wouldn't notice and flags what they would.
Drop Applitools Eyes into an existing Playwright test and replace a screenshot assertion with a visual checkpoint. No rewrite required.
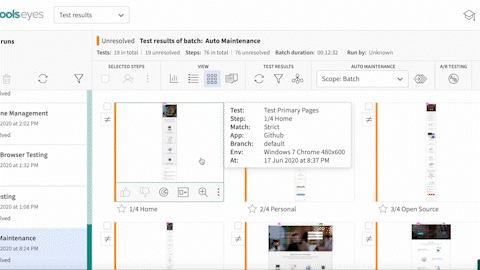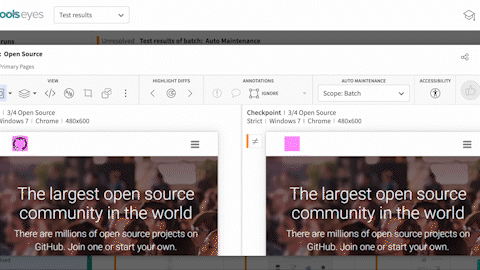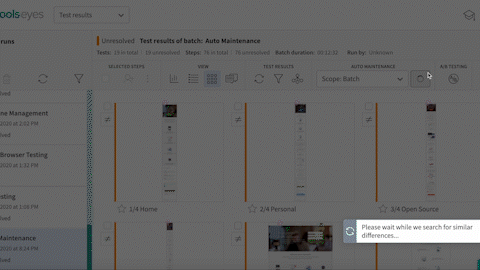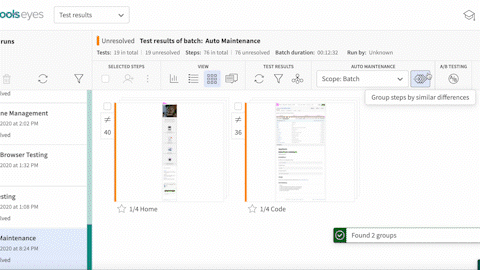
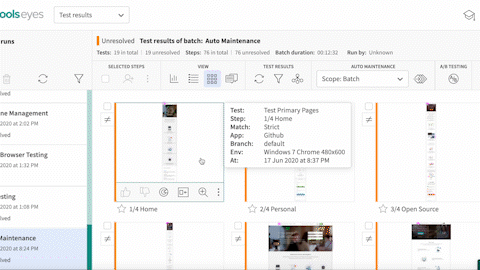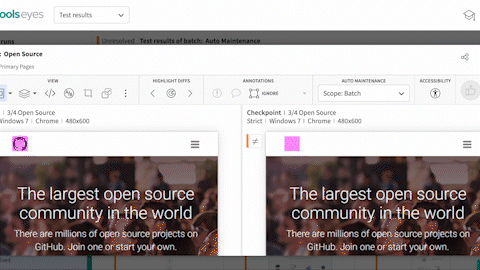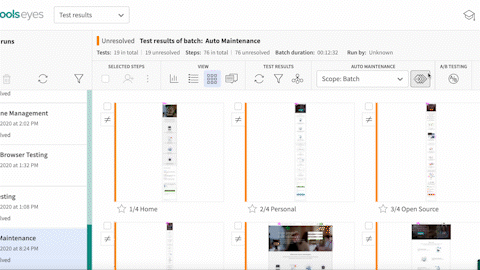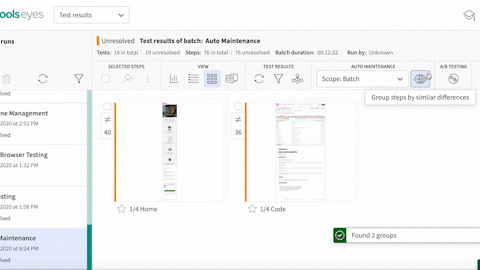
Group by Diff batches near-identical failures so you can accept or reject hundreds of them in one action instead of reviewing each diff.
Meaningful differences only
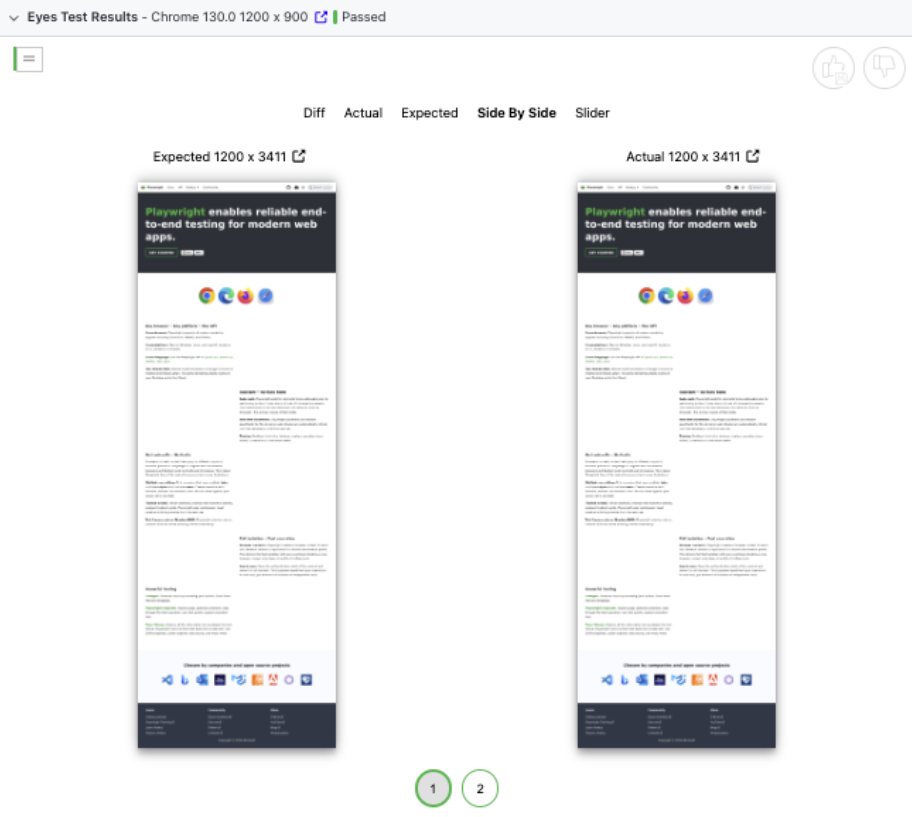
Applitools Eyes ignores rendering noise like anti-aliasing and sub-pixel shifts, so a font-rendering difference between CI and your laptop doesn't fail a test that's actually correct.
Match levels per checkpoint
Set Strict for pixel-level precision, Layout when position matters more than content, or Dynamic to validate that a date or account number still fits its pattern without asserting on the exact value.
Cloud-hosted baselines
Baselines live in Applitools, not your repo, so an intentional UI change doesn't mean a pull request full of updated screenshot files.
Group by Diff
Accept or reject a batch of near-identical failures in one action, for when a single CSS change breaks a hundred checkpoints the same way.
Ultrafast Grid
Render the same checkpoint across Chrome, Firefox, Safari, Edge, and mobile viewports in parallel, without installing or maintaining a browser locally.
One test, every environment
Write the test once against Playwright, and let the grid handle cross-browser and cross-device coverage instead of duplicating your suite per target.
Root cause analysis
When a checkpoint fails, see the DOM and CSS change behind it directly in the result, so you're debugging the actual cause, not guessing from a diff image.
Support for A/B testing
Register multiple baseline variants for the same checkpoint, so an active experiment doesn't produce a false failure the way a single-baseline comparison would.
Applitools works with 50+ major testing frameworks and languages, source code tools, CI/CD tools, and collaboration tools.

Extend the same visual checks across web, mobile web, and component libraries, so a regression doesn't slip through in a format you didn't think to test.
Applitools Eyes runs inside your existing Playwright config and CI pipeline, so visual checks execute alongside the rest of your suite. No separate tool to invoke.
Visual comparisons run locally within your environment. Component snapshots are never sent to an external model or used for training.
The same screen, device, and test always produce the same result, so a pass is something you can trust and a failure is a real regression, not a flaky run.
Visual AI ignores rendering noise like anti-aliasing and sub-pixel shifts, and flags only the differences a real user would notice.
See the exact DOM and CSS change behind a failure, directly in the result, so you know what broke without re-running the test in a debugger.
